with the market-leading bioprocess intelligence software for R&D and manufacturing

1500+ bioprocess data sets analyzed with DataHowLab
13 of 20 top pharma organizations trusted DataHowLab
10 years of developing DataHowLab with industry

Why run experiments when you have so much process knowledge available?

DataHowLab transforms bioprocess data into contextualized, reusable organizational knowledge. Decisions draw on everything your organization has already learned, so each new project needs fewer experiments and every decision carries less risk.

Topic
Today
With DataHowLab
Starting point
Each new project starts from scratch, requiring investment in extensive experimental work
Each new project starts from everything your organization already knows
Modeling approach
Statistical models which rely purely on available data
Bioprocess hybrid models which encode scientific knowledge and require less data
New experiments
Needed for every open question
Needed only where knowledge is limited and designed to answer targeted questions
Decision risk for scientists
High risk: decisions based on limited data and information generated in project
Low risk: Decisions made based on project insights and knowledge from past projects
Scale up
Experiment-heavy with limited use of small scale knowledge
Scale-up with 1-2 large-scale runs by leaning on small scale and historical data
After the project
Knowledge captured in the project report. Key knowledge containers (models/data/insights) are lost.
Knowledge is an organizational asset, delivering returns to the next projectExplore DataHowLab

Transforming what you know into the best next step

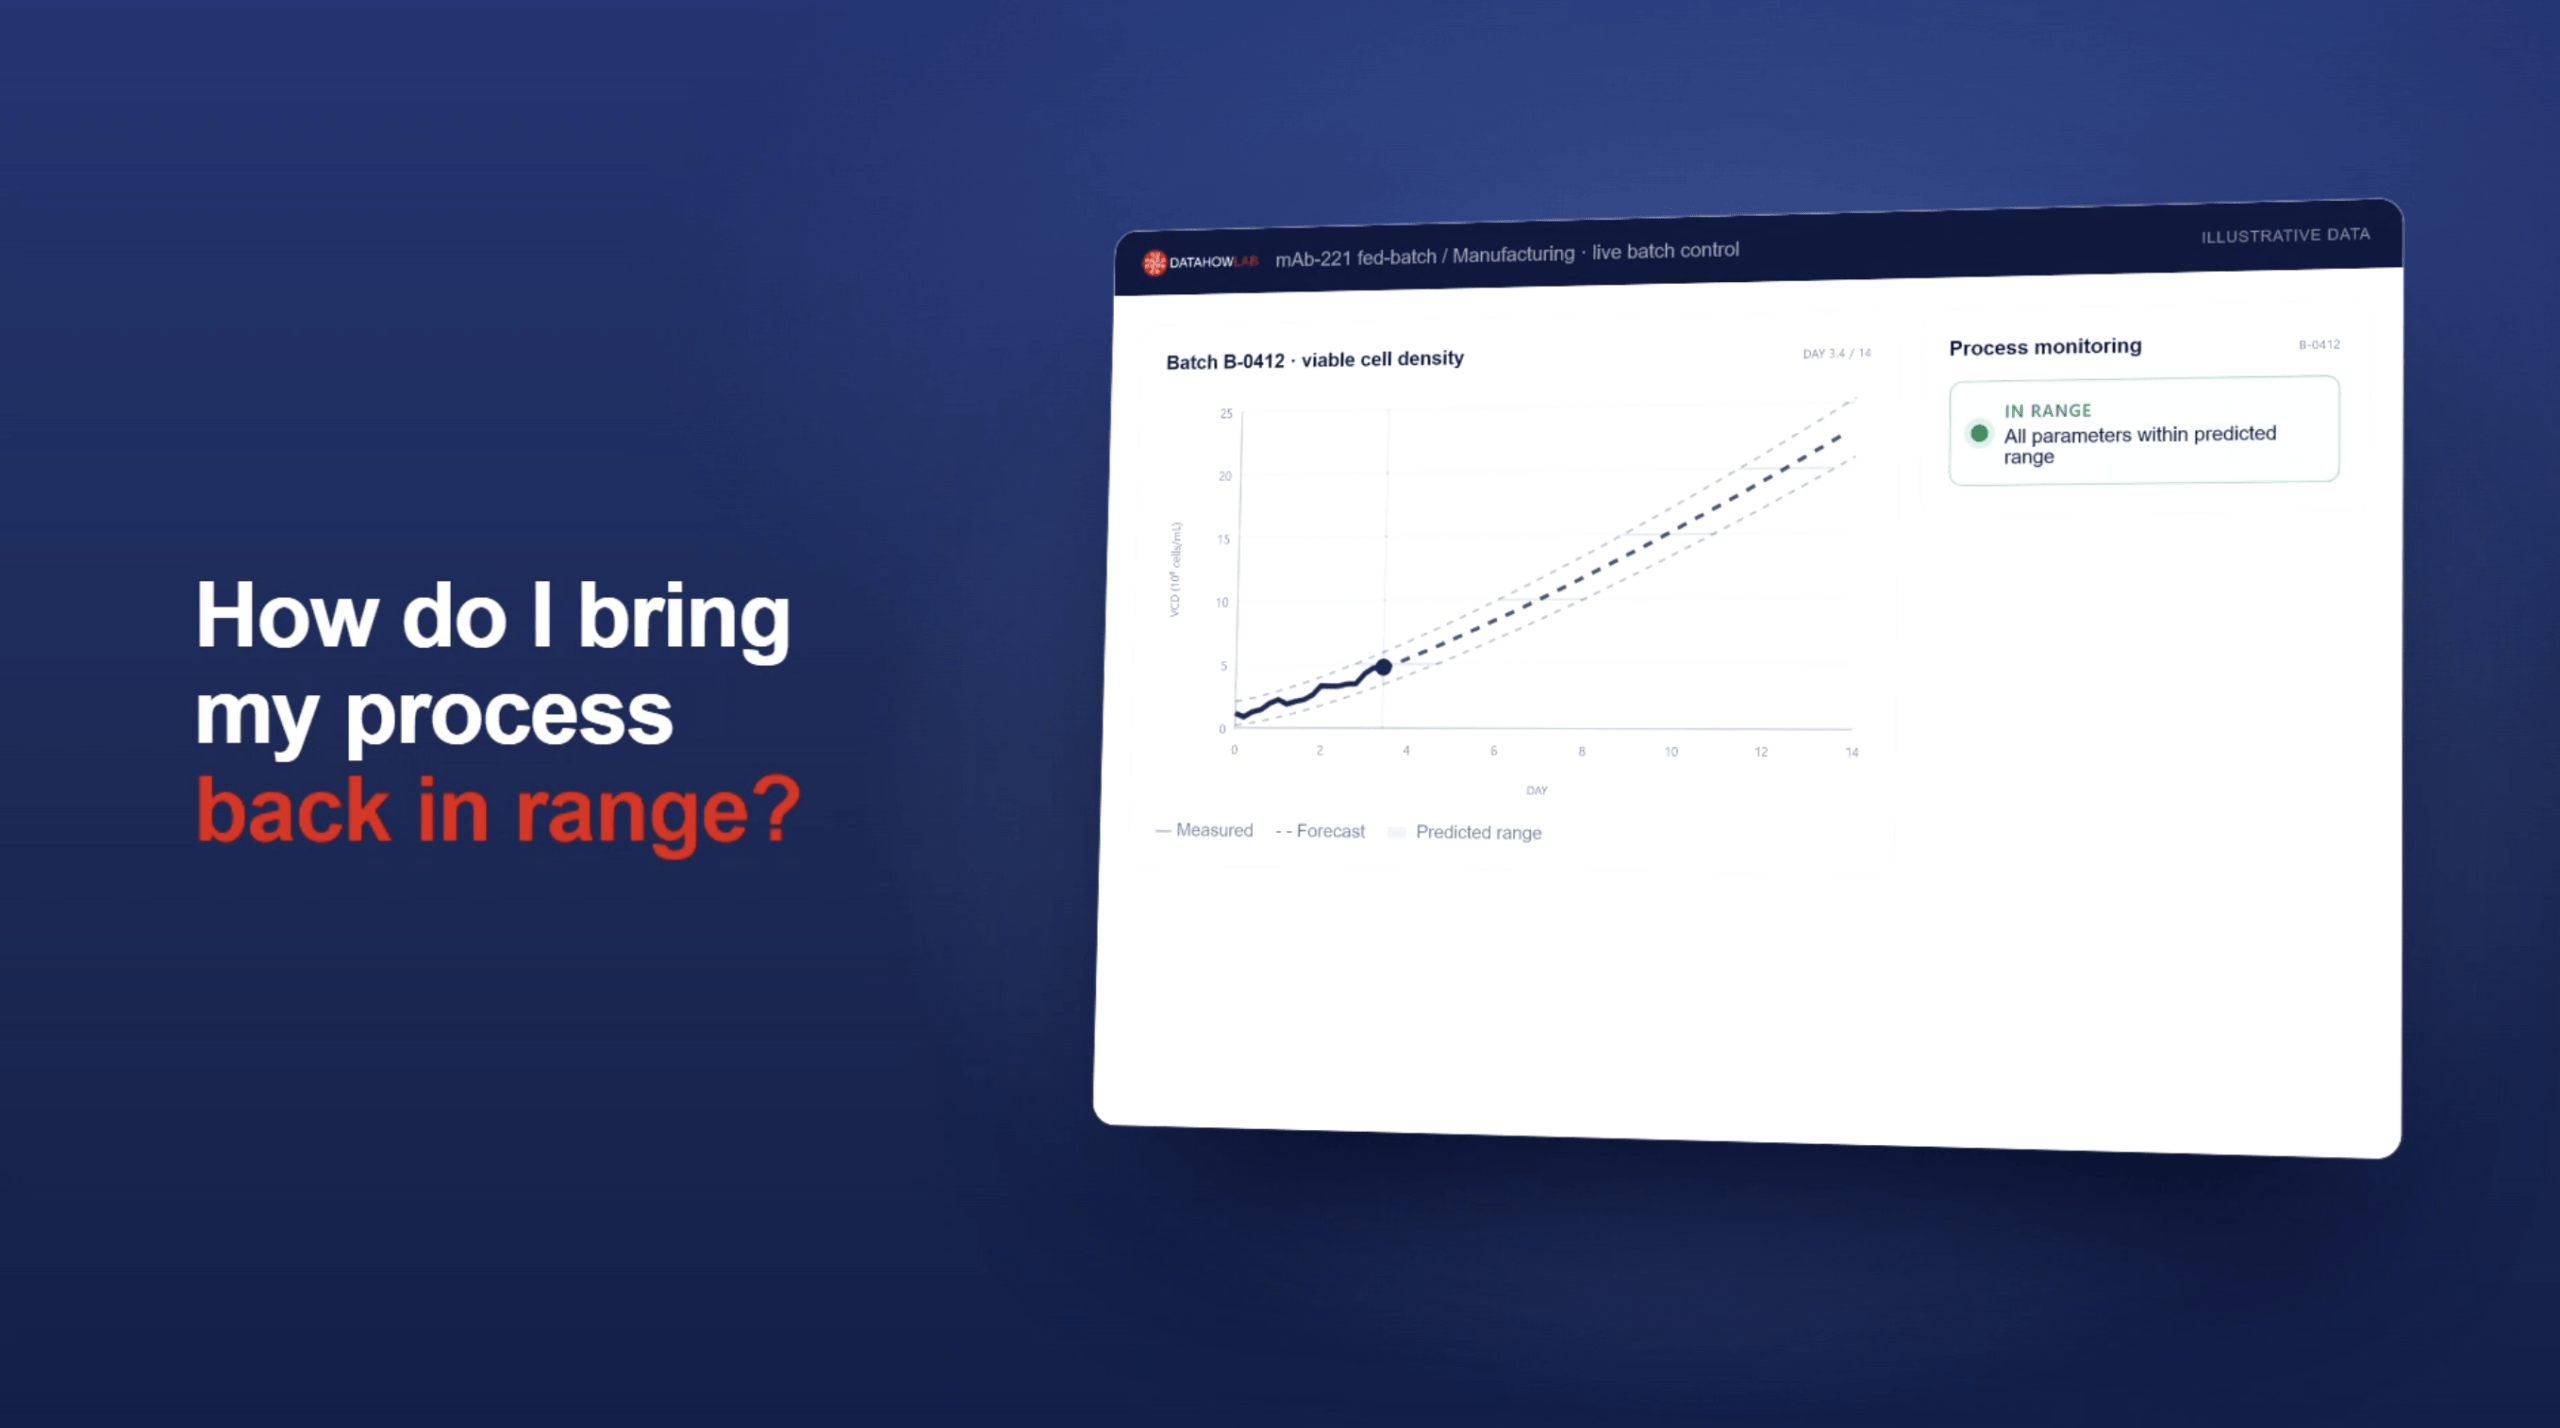
DataHowLab turns your bioprocess knowledge into clear recommendations based on your objectives. Make the best decision and continue with confidence backed by data-driven intelligence.

40% fewer experimental runs than DOE, with no loss of bioprocess insight
“By using DataHowLab’s hybrid models and process knowledge from past projects, we demonstrated the potential to cut experimental runs by at least 40% compared to DOE, without compromising on process insight or model quality. Our ultimate goal is to have DataHowLab connected to our ELN databases and integrated into every client project.”
Portrait of Alix Lecomte
Alix Lecomte Upstream Process Development Scientist, KBI Biopharma Watch the talk
~50% fewer bioreactors and ~50% less experimental time in BLA-enabling process characterization using hybrid modeling.
Presented by AbbVie Digital Bioprocessing Symposium 2026 Watch the talk
Transfer learning on historical clone screening data made clone selection 2x faster, with more than 50% fewer experiments.
Clone selection case study Mammalian clone selection Read the case study
One laboratory study skipped, a ~6-week reduction in development time, using knowledge transfer from historical platform data.
Presented by BMS Digital Bioprocessing Symposium 2025 Watch the talk
3 months saved, ~$50k in supplies, 33% fewer development runs, with improved quality, using model-first clone selection for an ADC in a non-platform cell line.
Presented by BMS Xtalks webinar 2026 Watch the webinar
Transfer learning in DataHowLab predicted each new strain’s large-scale behavior from small-scale data, with 50% fewer experiments at ambr250 scale.
Case study with Procelys by Lesaffre Microbial strain screening Read the case study
Hybrid modeling is now applied to every first-in-human program, as part of a model-first approach used across early- and late-phase development.
Presented by BMS Xtalks webinar 2026 Watch the webinar

Increase operational efficiency at every stage of the process lifecycle

Measured results from industrial customer use cases, from early-stage development to pilot and commercial manufacturing.

Explore Resources
Bioprocess optimization With Bristol Myers Squibb
3x fewer experiments 35% better CQA prediction

Head-to-head against industry black-box models on 48 runs at 5L, 12 CPPs and 18 CQAs: hybrid models needed 10 experiments where black-box models needed 30.

Scale-up With Wheeler Bio
1 large-scale run needed 50% better large-scale prediction accuracy

From 11 ambr15 runs, adding a single 10L run to the model was enough to predict the remaining 10L runs, instead of a full large-scale campaign.

Bioprocess digital twins With Merck KGaA
+50% higher VCV vs. standard operation <0.5 prediction error of perfusion dynamics

A hybrid-model digital twin connected directly to a 24-reactor ambr®250 perfusion system ran the bioprocess autonomously as a self-driving system.

The intelligence platform built uniquely for bioprocessing

DataHowLab democratizes advanced bioprocess intelligence, putting it directly in the hands of bioprocess scientists, across every bioprocess format you develop.

Explore Applications
Available for
Mammalian cell culture
Microbial
Gene therapy
Cell therapy
mRNA

Your bioprocess data is your most valuable asset. We protect it like one.

DataHowLab is built for the confidentiality expectations of biopharma, from early development data to manufacturing records.

ISO 27001Certified information security management, to the leading international standard
Certified security managementInformation security is managed and audited against ISO 27001, with processes that meet strict regulatory and industry expectations.
Secure cloud platformDataHowLab is a secure cloud-native platform, available as SaaS or on-prem.
Data PrivacyYour data is your data. We use single-tenant deployments so your data is only ever used by you. Our models are provided untrained, and your data is never used for general model training.

Realize what is possible on your bioprocess